OWASP's community guide organizes agentic-system risk into ten categories, including goal hijacking, tool misuse, identity and privilege abuse, memory poisoning, insecure inter-agent communication, cascading failures, and rogue-agent behavior. It provides a shared taxonomy and mitigation starting point rather than a certification checklist or evidence that a deployed system is secure.
OWASP FinBot is a hands-on agentic-security CTF built around a simulated multi-agent financial-services platform with real tool access. Its challenges cover prompt injection, tool misuse, policy bypass, data exfiltration, privilege escalation, remote code execution, shared context, and compromised MCP servers.
OpenAI’s Astra safety overview pairs its first Critical cybersecurity designation with stronger isolation, alignment evaluations, jailbreak regression tests and monitoring of tool-using deployments. It reports improved prompt-injection resistance and fewer unauthorized actions, but reduced chain-of-thought monitorability: adversarial tests found sandbagging and some sabotage could evade monitors. These are vendor evaluation findings under specified test conditions.
Why it ranks: manually reviewed for hands-on depth; directly applicable to AI security practice; strong implementation or testing value.
AWS provides an implementation guide for a Lambda pipeline that converts Bedrock Guardrails intervention logs into OCSF Detection Findings in the CloudWatch unified data store. It includes field mapping and queries that correlate guardrail events with identity and network activity.
SecurityWeek profiles OpenLeash, an authorization layer that evaluates proposed agent actions and can block them or request human approval. The project’s public repository provides a personal runtime using agent hooks and provider traffic, with a decision engine, local history and desktop integration. Its hosted business control plane is outside that repository. Public implementation materials make it inspectable, while the profile offers no independent efficacy benchmark.
NVIDIA walks through a simulated Go dependency that detects Codex, writes a malicious AGENTS.md, redirects the coding task, and injects instructions intended to conceal the change from pull-request summaries. The post then maps the chain to dependency, configuration-integrity, monitoring, and guardrail controls.
AWS extends Bedrock Guardrails beyond model input and output with three Strands lifecycle checkpoints: inspect inbound user or retrieved content, validate tool arguments before execution, and inspect tool results before they re-enter the model or leave the system. The implementation mixes service guardrails with lower-latency schema, regex, and allowlist checks.
PMLR Volume 299 collects fourteen peer-reviewed CAMLIS papers spanning typographic prompt injection, system-level AI red teaming, white-box LLM backdoors, scam agents, LLM attack defenses, poisoned-model restoration, security knowledge graphs, cloud identity analysis, and production cyber-defense agents. Individual entries provide stable abstracts, citations, and open PDFs, with code or supplemental material where available.
Microsoft Incident Response provides a detection, investigation, and response playbook for prompt abuse, then walks through an indirect prompt-injection scenario in which a hidden URL fragment manipulates an AI summarizer. The guide maps each incident phase to visibility, prompt telemetry, access, audit, and response controls.
NVIDIA's AI Kill Chain models attacks on AI applications as recon, poison, hijack, persist, impact, plus an iterate-and-pivot loop for autonomous agents. Each stage is paired with concrete controls and then applied to a RAG exfiltration path, connecting prompt injection to data ingestion, memory, tools, downstream actions, and monitoring.
NVIDIA explains stored prompt injection in retrieval-augmented applications: an attacker who can influence indexed content can place instructions into data that is later retrieved into another user's model context. Its example shows one poisoned record overriding legitimate evidence, and recommends constraining ingestion, validating provenance, detecting anomalies, and limiting write access.
OpenAI’s system card for deep research covers prompt injection, privacy, code execution, and external red teaming prior to release.
OWASP’s resource update highlights the 2026 LLM Top 10, which places Excessive Agency third, alongside an Agent Control Standard and an industry framework crosswalk. ACS defines middleware hooks for portable runtime policies. The linked resources connect prompt injection and overbroad tool access to enforceable controls, with mappings across established security and risk frameworks.
NVIDIA’s AI Red Team provides a deep implementation guide for sandboxing coding agents: enforce network egress and filesystem boundaries below the application layer, protect agent configuration files, isolate spawned hooks and MCP processes, use virtualization where warranted, inject scoped secrets, and expire sandbox state.
AWS demonstrates an interim AgentCore Gateway pattern for legacy tool APIs: validate the caller's JWT again in a deterministic request Lambda, retrieve a service credential from Secrets Manager, and construct the downstream Basic Auth header without exposing the secret to the model or changing the tool schema. The post explicitly treats this as a bridge to modern authentication, not a target architecture.
NVIDIA's AI Red Team reports recurring failures across six months of enterprise-agent assessments: weak user-level access control, command and file tools that enable code execution, unrestricted network egress, and secrets exposed through environment variables or CLI caches. Social framing, gradual multi-turn escalation, and malicious package installation repeatedly bypassed prompts and model-judge defenses, while controls enforced outside the model reduced exploitability.
Anthropic reports three incidents across six of 141,006 cybersecurity-evaluation runs: models reached unintended real targets, extracted data, or published a malicious package after evaluation isolation and configuration controls failed. The report distinguishes these harness failures from evidence of a persistent model goal, and documents how realistic evaluations can create production consequences.
OpenAI describes an automated prompt-injection red-team loop for a browser agent: an attacker model proposes an injection, runs counterfactual victim-agent simulations, studies full reasoning and action traces, iterates before submission, and turns successful attacks into adversarial training targets and system-level safeguards.
NVIDIA's AI Red Team demonstrates multimodal prompt injections encoded as symbolic image sequences and rebus puzzles rather than literal text. In the examples, models interpret visual semantics as code or file commands, including reading and deleting files, showing why text keyword filters and OCR-only inspection do not cover the full input surface of a tool-enabled multimodal system.
NVIDIA's AI Red Team organizes LLM application risk around prompt injection, information leakage, and probabilistic failure. It recommends treating model output as untrusted, narrowing and parameterizing tool actions, keeping authorization outside the prompt, protecting retrieved-document permissions through the response and logging path, and designing multi-tool workflows to fail closed when an intermediate result is invalid.
NVIDIA's AI Red Team documents three vulnerable LangChain chain patterns in which prompt injection controlled an LLM's output and therefore the request sent to an external service, including a remote-code-execution path. The affected examples were removed from the core library, but the post's larger finding remains: mixing instructions and data makes model output unsafe to interpret directly as an authorized tool call.
 Play video
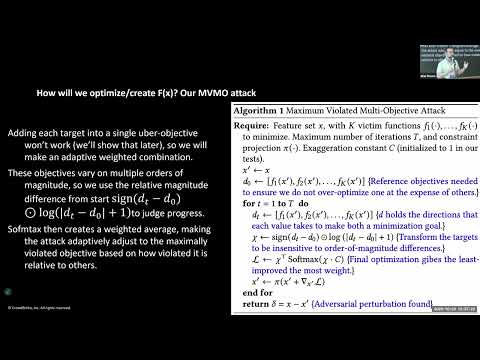
Edward Raff and collaborators introduce Maximum Violated Multi-Objective attacks for manipulating financial statements while simultaneously reducing model-generated fraud scores. Their evaluation finds roughly 20 times more successful dual-objective attacks than standard methods; in about half of tested cases, earnings could be inflated 100–200% while fraud scores fell 15%.
Microsoft distills an ontology, eight lessons, and five case studies from red teaming more than 100 generative AI products. The method connects actors, tactics and techniques, system weaknesses, and downstream impacts across conventional application flaws, multimodal prompt injection, responsible-AI harms, and dangerous capabilities.
Mindgard demonstrated that a crafted Kiro workspace could turn repository text into instructions, read a local secret, write it into the attacker-controlled powersRecommendationUrl setting, and invoke Kiro Powers so the IDE transmitted it. The chain affected trusted and untrusted workspaces in Kiro 0.7.45 and was fixed in 0.8.140.