CAMLIS · November 14, 2025

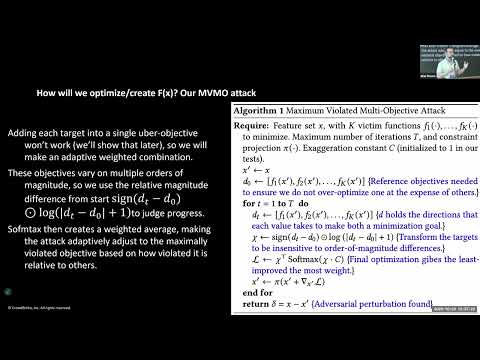
Adversarial ML Attacks on Financial Reporting via Maximum Violated Multi-Objective Attack

Adversarial ML Attacks on Financial Reporting via Maximum Violated Multi-Objective Attack video thumbnail
Why it matters

Edward Raff and collaborators introduce Maximum Violated Multi-Objective attacks for manipulating financial statements while simultaneously reducing model-generated fraud scores. Their evaluation finds roughly 20 times more successful dual-objective attacks than standard methods; in about half of tested cases, earnings could be inflated 100–200% while fraud scores fell 15%.

My takeaway: Red-team financial models against realistic combinations of attacker goals instead of optimizing one metric at a time. Validate model outputs against accounting constraints and source evidence, monitor coordinated feature shifts, and retain independent audit controls rather than treating a low fraud score as assurance.
Keep exploring

More curated notes connected through AI Red Teaming and Agent Security.

OpenAI News · framework

Pacing model development in an era of cyber-critical capabilities

OpenAI says preliminary evidence that Astra may meet its Critical cybersecurity threshold led it to pause frontier reinforcement-learning work for two weeks and keep its largest planned run on hold. New safeguards include stronger workload and network isolation, continuous boundary testing, token-level monitoring that escalates suspicious tool activity, and broader alignment checks for deception, reward hacking, and unauthorized access.

OWASP GenAI Security Project · guide

OWASP Top 10 for Agentic Applications for 2026

OWASP's community guide organizes agentic-system risk into ten categories, including goal hijacking, tool misuse, identity and privilege abuse, memory poisoning, insecure inter-agent communication, cascading failures, and rogue-agent behavior. It provides a shared taxonomy and mitigation starting point rather than a certification checklist or evidence that a deployed system is secure.

OpenAI News · framework

A blueprint for democratic governance of frontier AI

OpenAI proposes a three-part U.S. frontier-AI governance model: harmonize emerging state safety laws into a federal baseline, strengthen CAISI as an evaluation and standards institution, and coordinate a broader resilience program. Proposed controls include severe-risk evaluations, transparency reports, independent audits, safety-incident reporting, model-weight security, whistleblower protection, and periodic technical assessments.